Until today, Kitana told you what was wrong with an asset, and fixing it was still your job.
That is changing, because creative work now starts in AI tools: a launch post from Claude, a landing page update in Cursor, a campaign resized for five channels from the terminal. That work needs a brand review too, and if an agent made it, an agent can also fix it.
So we built the Kitana MCP server. Any MCP client (Claude, ChatGPT, Cursor, your terminal and many more) can now run a Kitana review, fix what she flagged and ask her to check again.
From diagnosis to fix
Kitana Lite launched as a reviewer: a score against your brand system, and where the work drifts. That is useful, but a report is a diagnosis, and someone still had to open the file and fix it.
With MCP, the review becomes a loop:
- Review. Your agent sends the asset to Kitana and gets back the score and the findings.
- Fix. The findings are exact enough to act on: a hex value, a weight, a clear-space ratio. The agent makes the changes.
- Check again. The agent sends the new version, and Kitana compares the two reviews, so you see what was fixed and what is still open.
Kitana still shows how and why an asset is off-brand; now your agent closes the gap.
What the loop looks like
Here is the loop on the Summer Frequencies poster, run from an agent in the terminal.
Review. The first review scores the poster 68, Needs Work. The accent is #4F86F7 where the brand accent is cobalt #1D4ED8, the headline uses three weights across its lines, and the logo has 0.6× the minimum clear space.
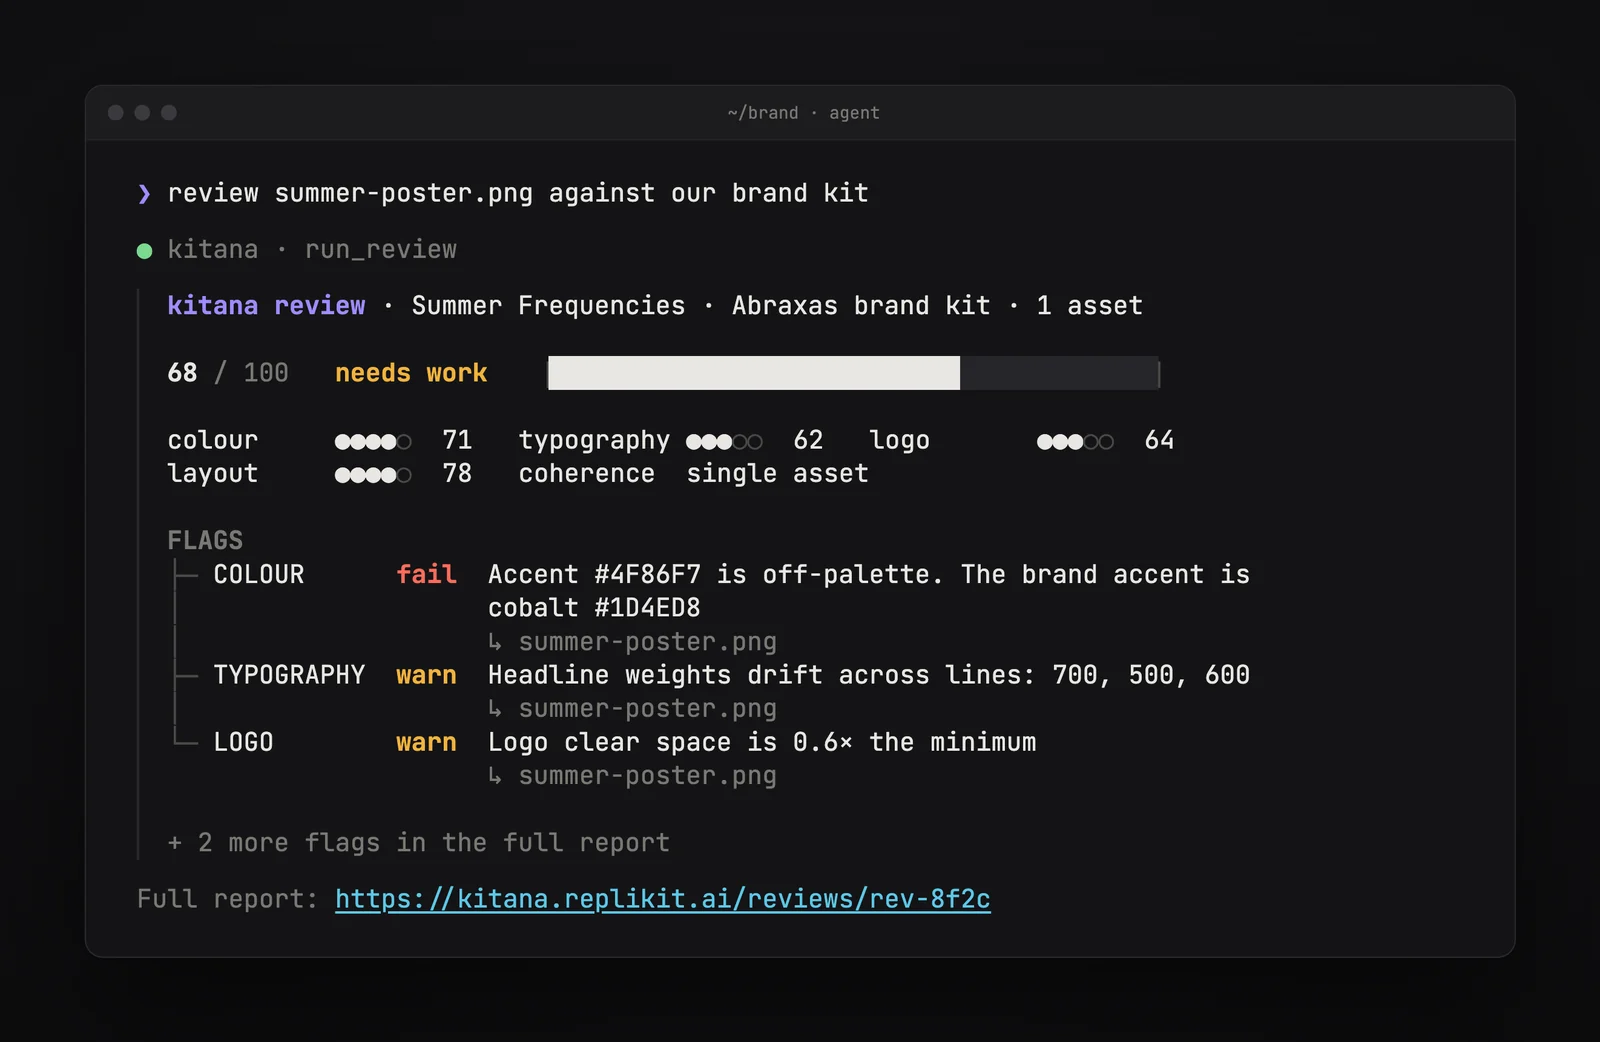
The review in the terminal.
Fix and check again. The agent sets the accent back to cobalt and gives the logo its full clear space, then asks Kitana to compare the two versions. The score goes from 68 to 87, from Needs Work to Good. Colour and logo are marked fixed, but the headline weights are still open, and Kitana says so.
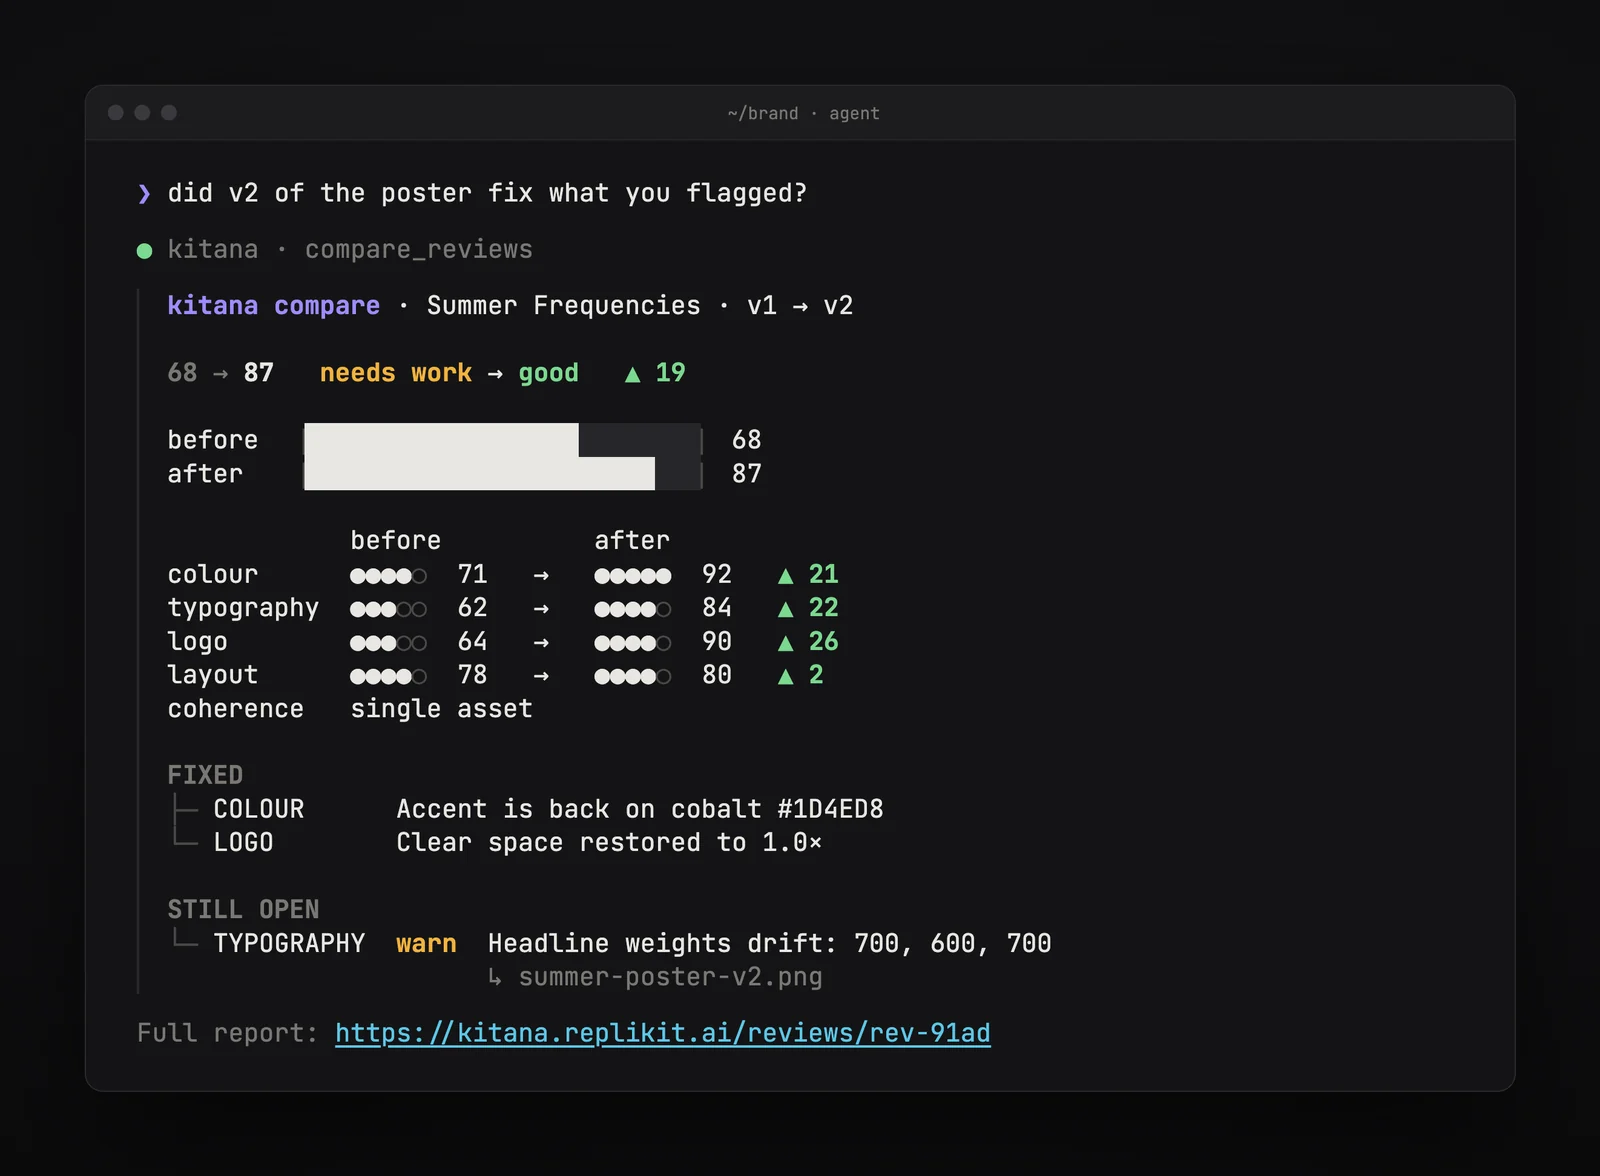
What changed per category, what was fixed, what is still open.
That last part matters, because any agent can say “done”. The part you can trust is a reviewer that checks the work and says what is not done.
See the trend. Because every review is kept, your agent can also answer questions about your brand over time. Ask how your score has moved since August, and Kitana returns the trend per category and your latest reviews.
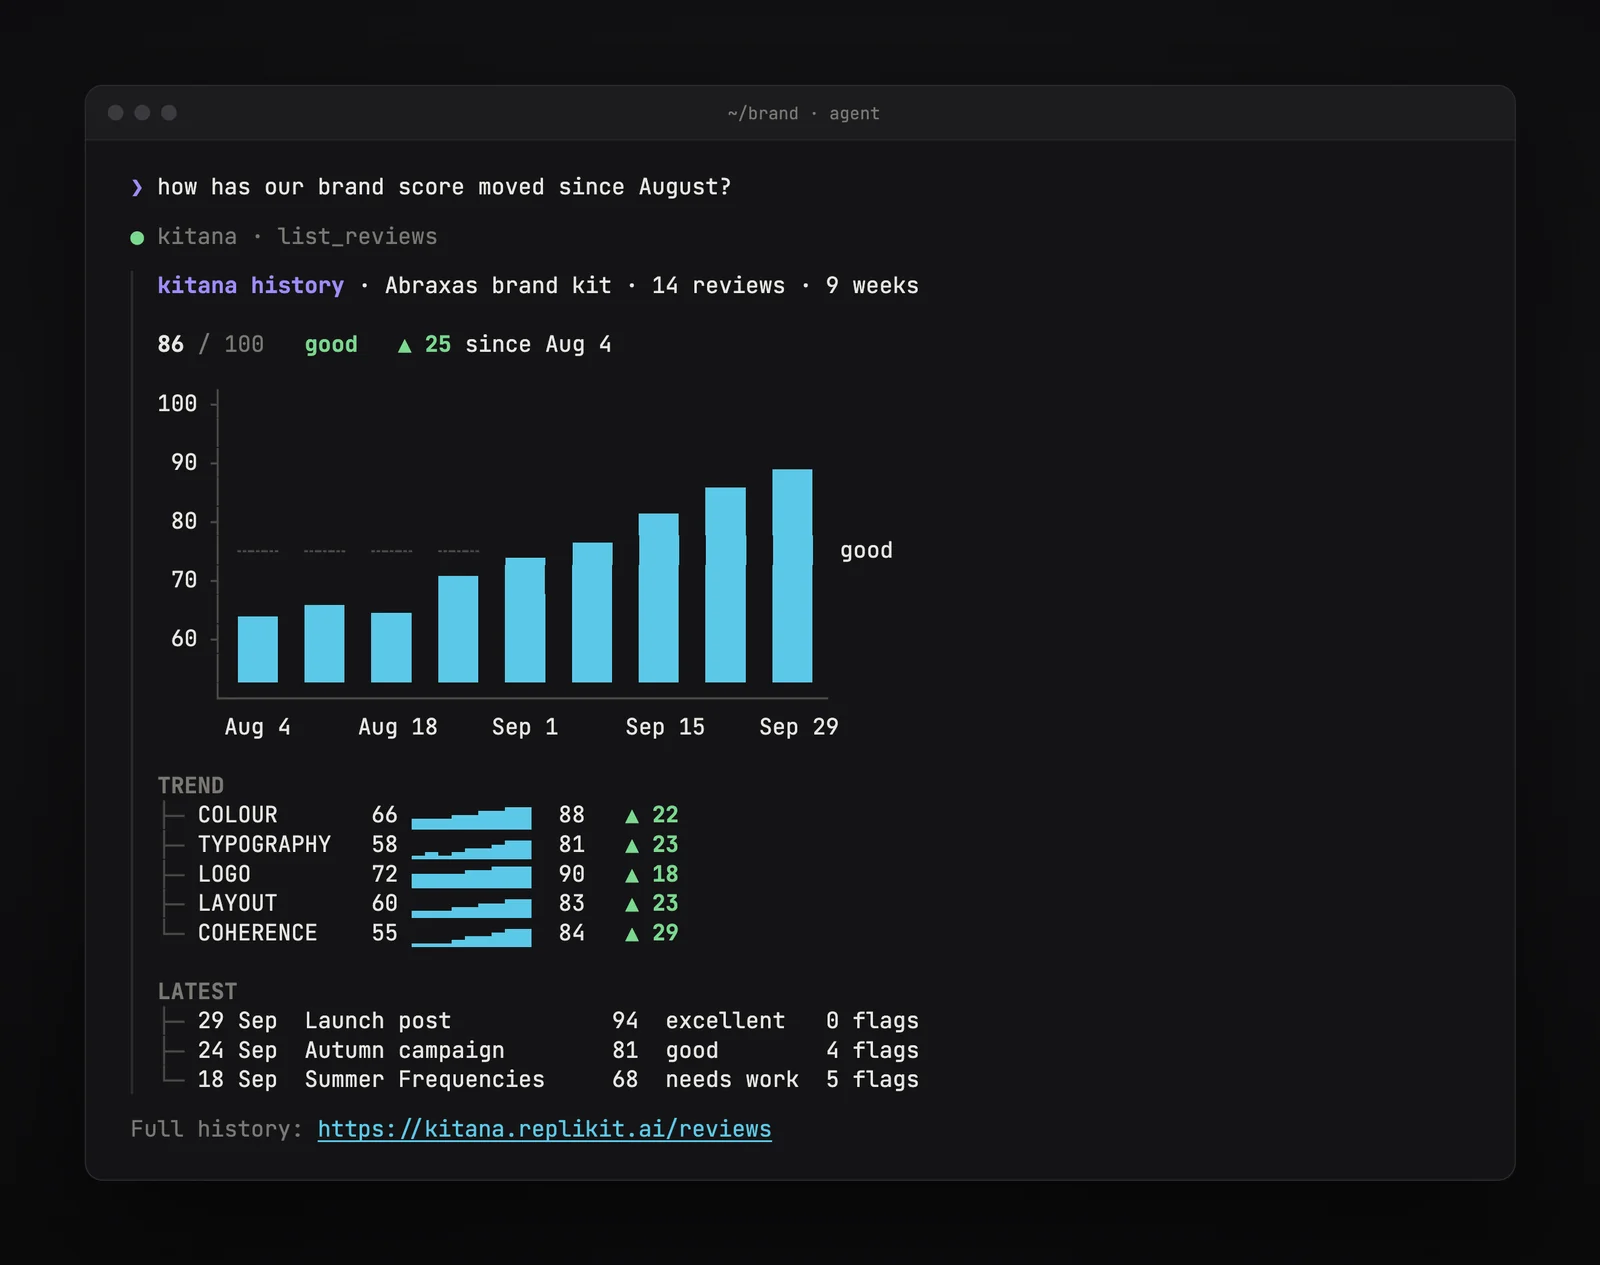
Fourteen reviews over nine weeks: 86 out of 100, up 25 since August 4.
In the tools you already use
Kitana works the same way in every client; only the shape of the answer changes. In Claude or ChatGPT, the review comes back as a card with the score, the categories and a link to the full report. In Cursor and the terminal, it comes back as a report formatted for the terminal.
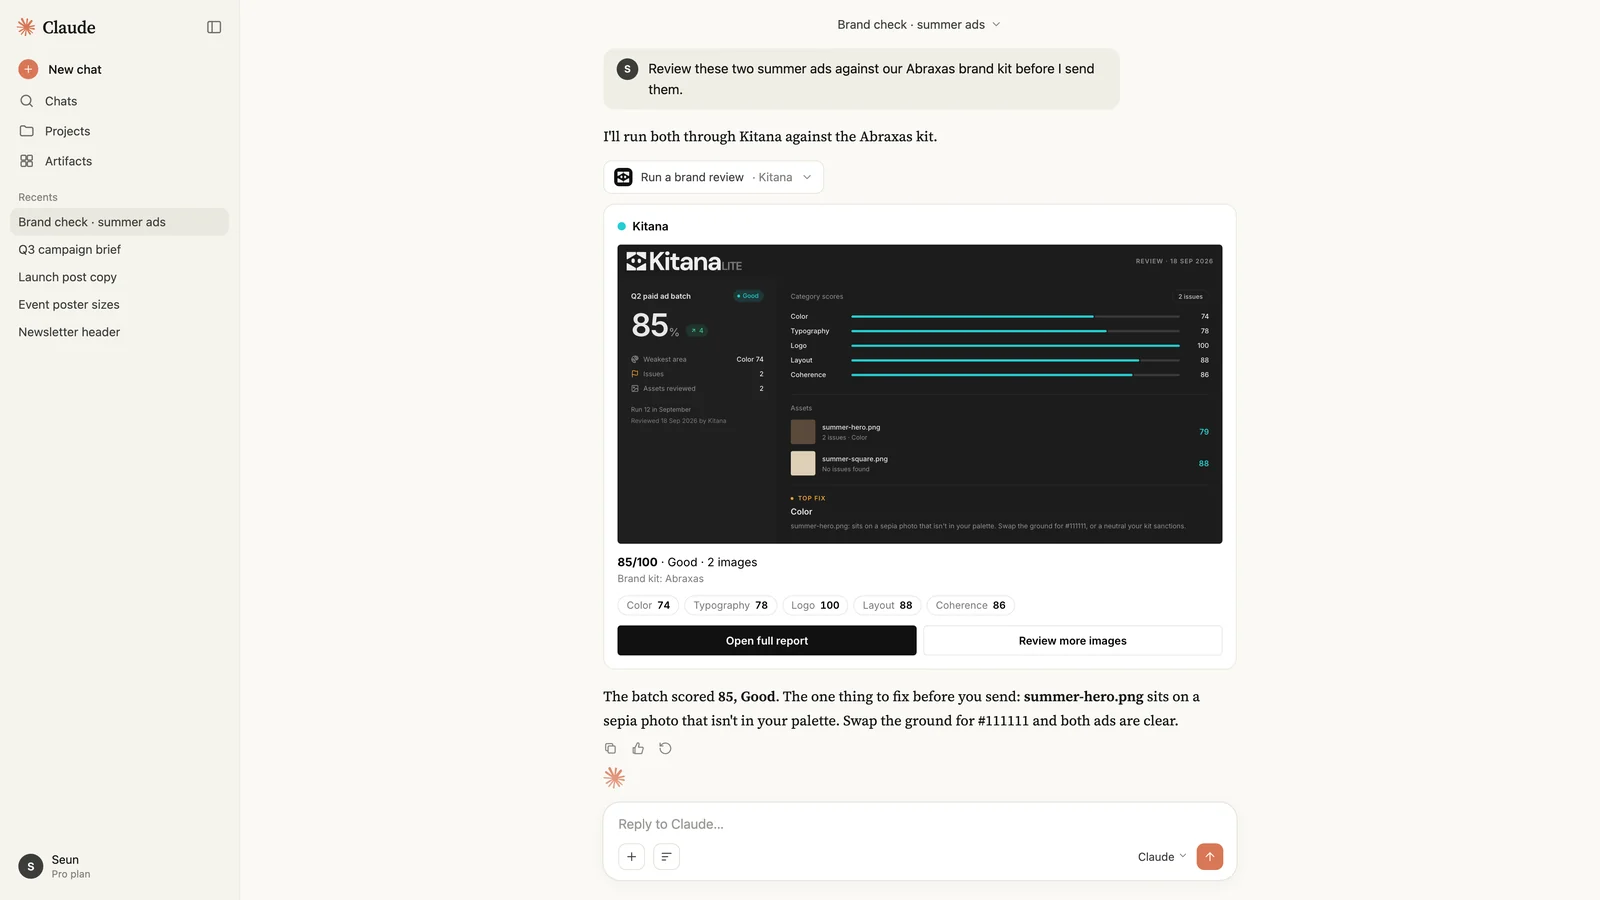
In Claude: a card, then the one fix to make before sending.
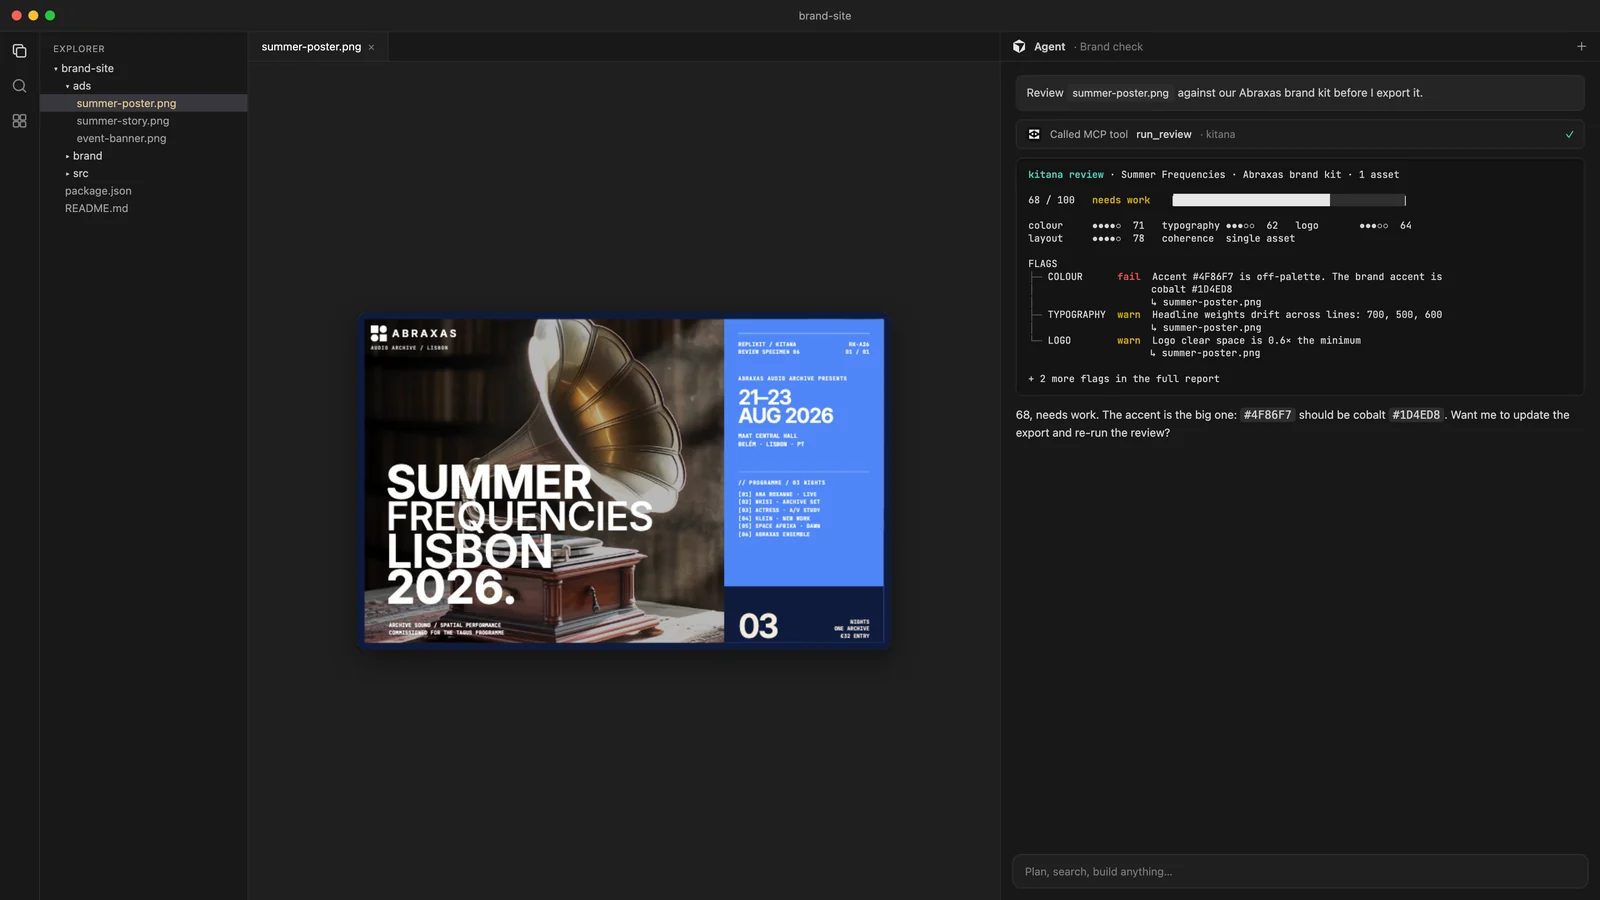
In Cursor: the review runs in the agent panel, next to the file it checks.
What your agent can do
The server gives your agent six tools:
run_reviewreviews 1 to 10 images against your brand kit and returns the score, the five category scores, the findings and a link to the report.compare_reviewscompares two reviews per category and says whether the two are comparable.list_reviewslists your workspace’s reviews, newest first.get_reviewreturns one review in full.switch_kitlists your brand kits and picks the one reviews use.prepare_uploadgives upload links for local files, for clients that cannot attach images.
Connect in a minute
The server is at https://mcp.replikit.ai. You sign in with your Kitana account in the browser, and there is nothing else to configure.
- Claude (claude.ai and Desktop): Settings → Connectors → Add custom connector, then paste
https://mcp.replikit.ai. - Claude Code: run
claude mcp add --transport http kitana https://mcp.replikit.ai, then/mcpto sign in. - Cursor: add the server to
~/.cursor/mcp.json:
{ "mcpServers": { "kitana": { "url": "https://mcp.replikit.ai" } } }- ChatGPT: Settings → Apps & Connectors → turn on developer mode → Create, then add
https://mcp.replikit.aiwith OAuth. - Any other MCP client: add
https://mcp.replikit.aias a remote HTTP server with OAuth.
The full setup guide has an example run and what each tool returns.
Plan and cost
MCP is part of RepliKit Pro ($39.99 a month, 20 reviews). A review from your agent costs one credit, the same as on the web, in Slack or in Figma. The other five tools are free, so your agent can compare reviews and read your history as often as it needs.
Connect Kitana to your agent. If you are new to Kitana, start with two free reviews on the web first.
First published on replikit.ai. Topics: Kitana, MCP, AI agents.